Using Datadog with Mergify
Send your merge queue metrics to Datadog to build dashboards, alerts, and reports alongside the rest of your observability data.

The Datadog integration pushes your merge queue metrics into your own Datadog account. Everything on the merge queue statistics page is available as a Datadog metric, so you can graph queue health next to your own service metrics and alert on it.
The integration is official and ships as a Mergify tile in Datadog’s integration catalog. Mergify writes the metrics to Datadog for you. There is no agent to install and nothing to run in your CI.
Prerequisites
Section titled Prerequisites-
A Datadog account, and permission to authorize integrations in it.
-
On the Mergify side, a plan that includes the Datadog integration, plus the GitHub organization
Ownerrole or the Integrations Admin delegated role.
Setting up the integration
Section titled Setting up the integration-
Install the Mergify tile from Datadog’s integration catalog and click Connect Accounts. The connection starts on the Datadog side, so the Connect Your Datadog Account button on the Mergify dashboard’s
Integrations → Datadogpage opens Datadog’s catalog rather than connecting from Mergify.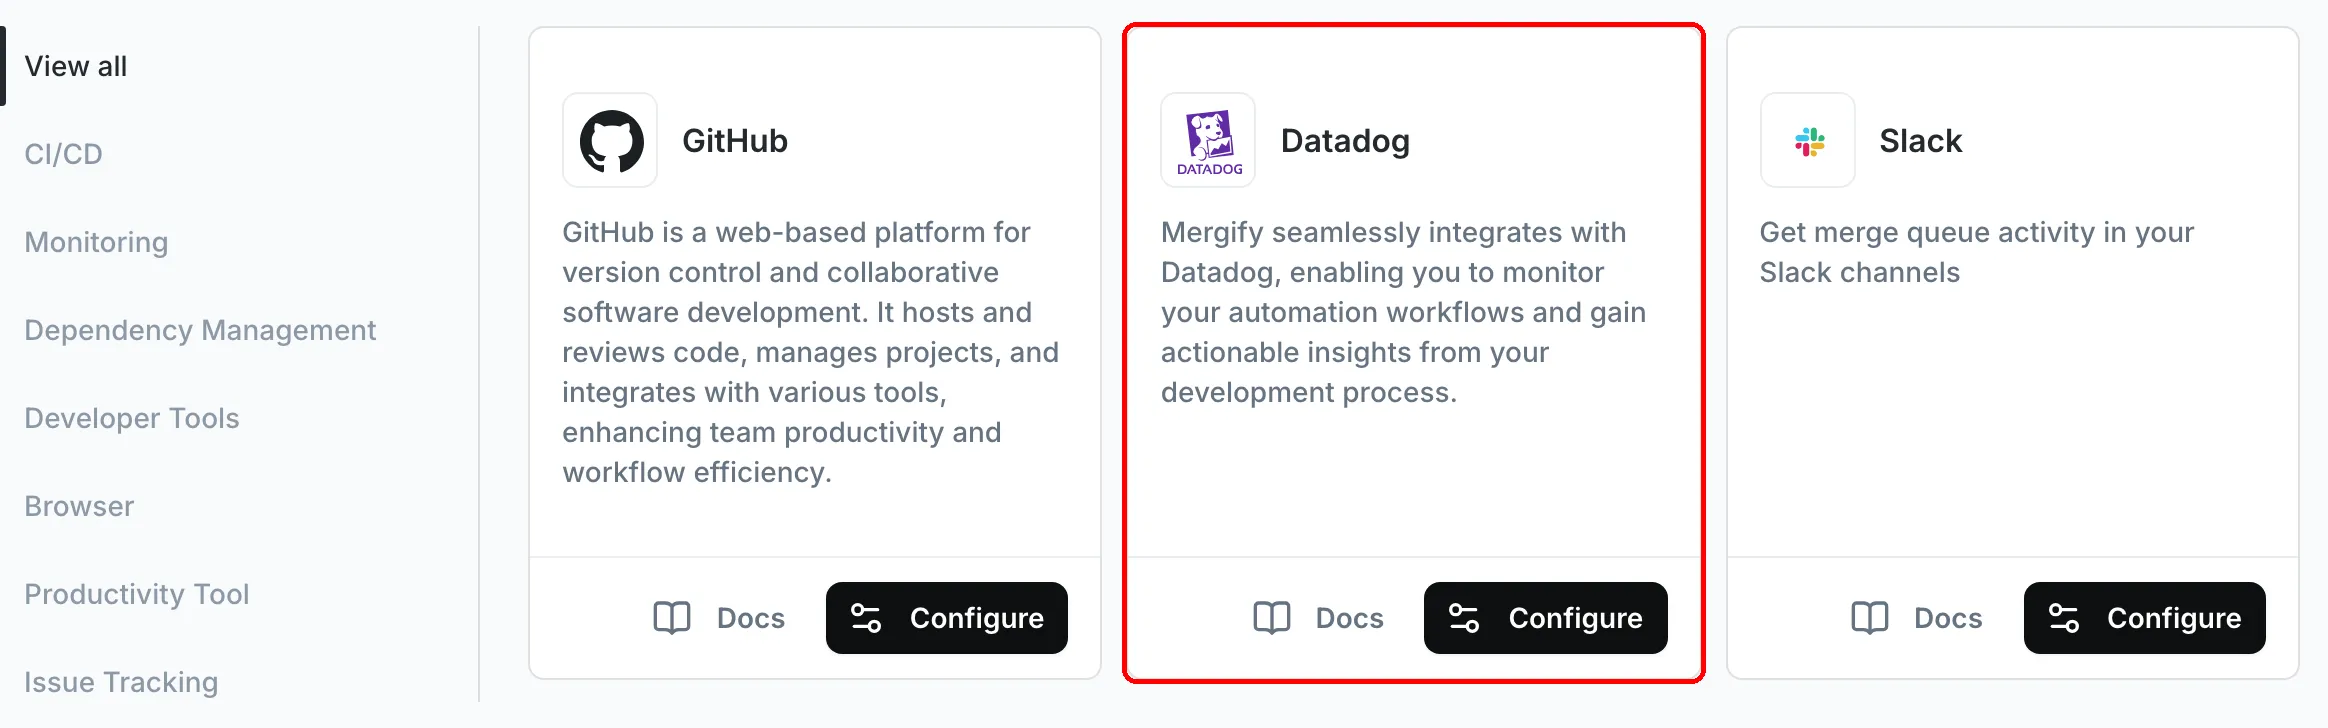
-
Authorize Mergify from the Datadog site your organization uses. Mergify supports US1, US3, US5, EU1, US1-FED, and AP1, and connects to whichever one you start from. Datadog then asks which GitHub organization to connect. Mergify creates an API key scoped to the integration and starts pushing metrics to that site.
-
Choose what to monitor. For each repository, select the merge queue base branches you want metrics for: the branches your queued pull requests target, such as
mainor a release branch.
Changing your Datadog site
Section titled Changing your Datadog siteTo switch the Datadog site your metrics go to, connect Mergify again from the site you want to move to, whether you are changing region or consolidating on a different Datadog organization. You do not need to know which site you are on today: reconnecting replaces the previous connection, whatever it was.
-
Sign in to Datadog on the site you are moving to.
-
In that account, install the Mergify tile and click Connect Accounts, exactly as you did when you first connected. There is no other way in: Mergify has no control that starts the change, and no API or CLI equivalent.
-
Choose the same GitHub organization as before, and authorize Mergify. The site you end up on is the one you started from, so there is nothing else to pick.
The Datadog permissions in Prerequisites apply again here, but to the Datadog organization you are moving to; the Mergify role requirement is unchanged.
Metrics start arriving on the new site at the next publication, and the old site stops receiving new points at the same moment. If you start the authorization and do not finish it, nothing changes: the previous connection stays in place until the new one completes.
What moves with you, and what does not
Section titled What moves with you, and what does notYour monitored repositories and their base branches are preserved. They belong to your GitHub organization rather than to the Datadog connection, so you do not have to select them again.
What stays behind on the old site:
-
The metrics already sent there. Mergify publishes new points from the moment you reconnect; it does not copy history to the new site.
-
Anything you built on those metrics. Dashboards cloned from the Mergify tile and any monitors you created live in the old Datadog organization. Recreate them on the new site.
-
The API key Mergify created. Reconnecting creates a new key on the new site and does not revoke the old one, so delete it yourself in the old Datadog organization once the switch is done.
Removing the integration
Section titled Removing the integrationTo stop sending metrics without disconnecting anything, remove every repository from the integration page in the Mergify dashboard. Metrics only cover the repositories you select, so an empty list stops them. The connection and the API key stay in place, ready if you add a repository back.
To disconnect entirely, delete the API key Mergify created in your Datadog organization. Mergify checks that key every minute and drops the connection as soon as it stops working, so nothing is left behind on either side. This is the only route that removes both halves, and it is done from Datadog: the Mergify dashboard has no disconnect control, because deleting the connection there would leave the API key live in your Datadog account.
Removing the key needs permission to manage API keys in Datadog. If that is someone else in your organization, ask them to delete it; clearing the repository list stops the metrics in the meantime.
Metrics
Section titled MetricsEvery metric is published every 5 minutes, and each point covers the 5-minute window it represents. A metric with nothing to report for a window is left out of that publication rather than sent as a zero. Gaps are normal on a quiet queue, and a no-data monitor will fire on one.
Every metric carries these tags:
| Tag | Description |
|---|---|
repository |
Full repository name, such as octo/hello-world |
branch |
The base branch the queued pull requests target |
queue |
Name of the queue rule |
priority_rule |
Name of the matching priority rule, when set |
The exception is priority_rule: running_checks.max and the two ci_runs.*
metrics are not aggregated by priority rule, so they never carry it.
Reference
Section titled ReferenceMetrics submitted as count are event tallies that Datadog sums exactly over any time range. Metrics submitted as gauge are peak values within the window.
| Metric | Type | Description |
|---|---|---|
mergify.queue.entered |
count | Pull requests that entered the queue |
mergify.queue.merged |
count | Pull requests merged out of the queue |
mergify.queue.exit_reason |
count | Pull requests that left the queue, tagged with exit_reason |
mergify.queue.size.max |
gauge | Largest the queue got |
mergify.queue.running_checks.max |
gauge | Most checks running at once |
mergify.queue.check_outcome |
count | Finished queue checks, tagged with outcome |
mergify.queue.checks_retries.recovered |
count | Failed checks that passed on retry |
mergify.queue.checks_retries.not_recovered |
count | Failed checks that failed again on retry |
mergify.queue.bisection.started |
count | Batch bisections started |
mergify.queue.merged_batches |
count | Batches the queue merged |
mergify.queue.skip_intermediate_results.batches_saved |
count | Batches merged on a later batch’s pass |
mergify.queue.skip_intermediate_results.batches_saved_during_speculative_checks |
count | In speculative checks |
mergify.queue.skip_intermediate_results.batches_saved_during_bisection |
count | In a bisection |
mergify.queue.skip_intermediate_results.eligible_batches |
count | Batches the option would have merged while off |
mergify.queue.skip_intermediate_results.eligible_batches_failed |
count | Eligible batches whose own checks failed |
mergify.queue.skip_intermediate_results.eligible_batches_aborted |
count | Eligible batches cut short of a pass |
mergify.queue.skip_intermediate_results.eligible_wait_time.sum |
count | Time eligible batches waited, in seconds |
mergify.queue.total_queue_time.sum |
count | Total time queued, in seconds |
mergify.queue.total_queue_time.count |
count | Queue sessions the sum covers |
mergify.queue.ci_runtime.sum |
count | Total CI runtime, in seconds |
mergify.queue.ci_runtime.count |
count | CI runs the sum covers |
mergify.queue.ci_runs.started |
count | CI runs the queue started |
mergify.queue.ci_runs.wasted |
count | CI runs the queue threw away, tagged with reason |
mergify.queue.batch_size.sum |
count | Total pull requests across batches |
mergify.queue.batch_size.count |
count | Batches the sum covers |
mergify.queue.breakdown.ci_runtime.sum |
count | Queued time spent running CI, in seconds |
mergify.queue.idle.capacity.sum |
count | Queued time spent waiting for capacity, in seconds |
mergify.queue.idle.schedule.sum |
count | Queued time spent waiting for a schedule, in seconds |
mergify.queue.idle.freeze.sum |
count | Queued time waiting on a freeze, in seconds |
mergify.queue.idle.count |
count | Queue sessions the breakdown sums cover |
Both outcome and exit_reason are success when the pull request merged or
its checks passed. Otherwise they name the reason the pull request left the
queue or its checks were aborted, such as checks_failed or pr_dequeued. The
integration’s README
lists every value. The reason on ci_runs.wasted is drawn from those same
abort reasons, and never success: a run is only counted there once the queue
has thrown it away.
merged_batches counts every batch the queue merged, and
skip_intermediate_results.batches_saved the ones among them that
skip_intermediate_results
merged on later batches’ passes, without their
own checks having to pass. batches_saved only moves when the option is on.
The two batches_saved_during_* metrics split those batches by where the skip
happened, and each place saves something different. During
speculative checks, the batch merged
while its own CI run, which has usually started already, was still going. The
skip saves the wait for that run, and saves CI runs only when that run would
have failed, since a failing batch makes the batches tested on top of it run
their CI again. During a
bisection, the
batch’s pull requests merged instead of being dequeued and tested again. A
batch Mergify recorded no place for, such as one merged before it started
recording them, or recorded both places for, counts in batches_saved alone,
so the two can sum to less.
On a queue that merges with
fast-forward or
merge-batch, a batch merged this
way before Mergify started recording such merges there counts as an ordinary
merge: it is in merged_batches but not in batches_saved or either of its
splits. Over a range that reaches back that far, the count and the share read
low.
The eligible_* metrics estimate, from the queue’s own history, what the
option would have done where it is off. They are the figures the
statistics page shows in place of the
saved batches. eligible_batches counts the batches the option would have
merged on later batches’ passes. Each of them waited for its own CI run instead:
-
eligible_batches_failedcounts those whose own checks then failed, timed out, or were interrupted, which made the batches tested on top of them run their CI again. Those are the runs the option would have saved. -
eligible_batches_abortedcounts those whose wait ended short of a pass, by a failure, a teardown, or a dequeue, so they did not merge as they were, though the option would have merged them. -
eligible_wait_time.sumis how long they waited in all, from the moment the option would have merged them until their own checks or something else ended the wait. There is no.countto go with it:eligible_batchesis its count.
No eligible_* metric is sent while the option is on, nor in
isolated mode, which does not support
it.
Querying the metrics
Section titled Querying the metricsAverages
Section titled AveragesThe duration and size metrics ship as a .sum and a .count rather than a
pre-computed average, so Datadog can recompute the real average over whatever
time range you graph. Divide a family’s own sum by its own count:
sum:mergify.queue.total_queue_time.sum{$repository} / sum:mergify.queue.total_queue_time.count{$repository}The same shape gives you average CI runtime (mergify.queue.ci_runtime.*) and
average batch size (mergify.queue.batch_size.*).
skip_intermediate_results.eligible_wait_time.sum is the one sum with no
.count: divide it by skip_intermediate_results.eligible_batches for the
average time an eligible batch went on waiting.
Check retry recovery rate
Section titled Check retry recovery rateThe share of failed checks that passed when retried:
sum:mergify.queue.checks_retries.recovered{$repository} / (sum:mergify.queue.checks_retries.recovered{$repository} + sum:mergify.queue.checks_retries.not_recovered{$repository})Share of batches merged on a later batch’s pass
Section titled Share of batches merged on a later batch’s passMergify sends no share metric, since a per-window rate cannot be summed back
over a longer range: derive it from the counts. Where skip_intermediate_results
is on, divide the batches it merged on a later batch’s pass by every batch the
queue merged:
sum:mergify.queue.skip_intermediate_results.batches_saved{$repository}.fill(zero) / sum:mergify.queue.merged_batches{$repository}A batches_saved of zero is not sent at all: .fill(zero) keeps the windows
without a saved batch at a share of zero.
Where the option is off, the share it would have had is out of every batch the queue would have merged with it on, meaning the batches the queue merged plus the eligible batches that did not merge as they were:
sum:mergify.queue.skip_intermediate_results.eligible_batches{$repository} / (sum:mergify.queue.merged_batches{$repository} + sum:mergify.queue.skip_intermediate_results.eligible_batches_aborted{$repository})This estimate reads low where an eligible batch was rebuilt and merged under another batch, since the eligible batch then counts in both terms of the sum. It can also read above 1, as an eligible batch whose own run passed can merge outside the range you graph, or not merge at all. For each branch, queue rule, and priority rule, the statistics page counts at least as many batches the queue would have merged as eligible ones, so its share stays at or under 100%.
Where queued time goes
Section titled Where queued time goesTotal queued time splits into CI runtime plus three kinds of waiting:
mergify.queue.breakdown.ci_runtime.sum # running CImergify.queue.idle.capacity.sum # waiting for a free check slotmergify.queue.idle.schedule.sum # waiting for a schedule to openmergify.queue.idle.freeze.sum # waiting for a freeze to liftGraphed together as a stacked area, they show what your queue is actually
waiting on. Divide any of them by mergify.queue.idle.count for a
per-pull-request average.
Because the three idle.* metrics are pure waiting time, sum:mergify.queue.idle.*.sum
gives you total wasted time without counting CI.
Dashboards and alerts
Section titled Dashboards and alerts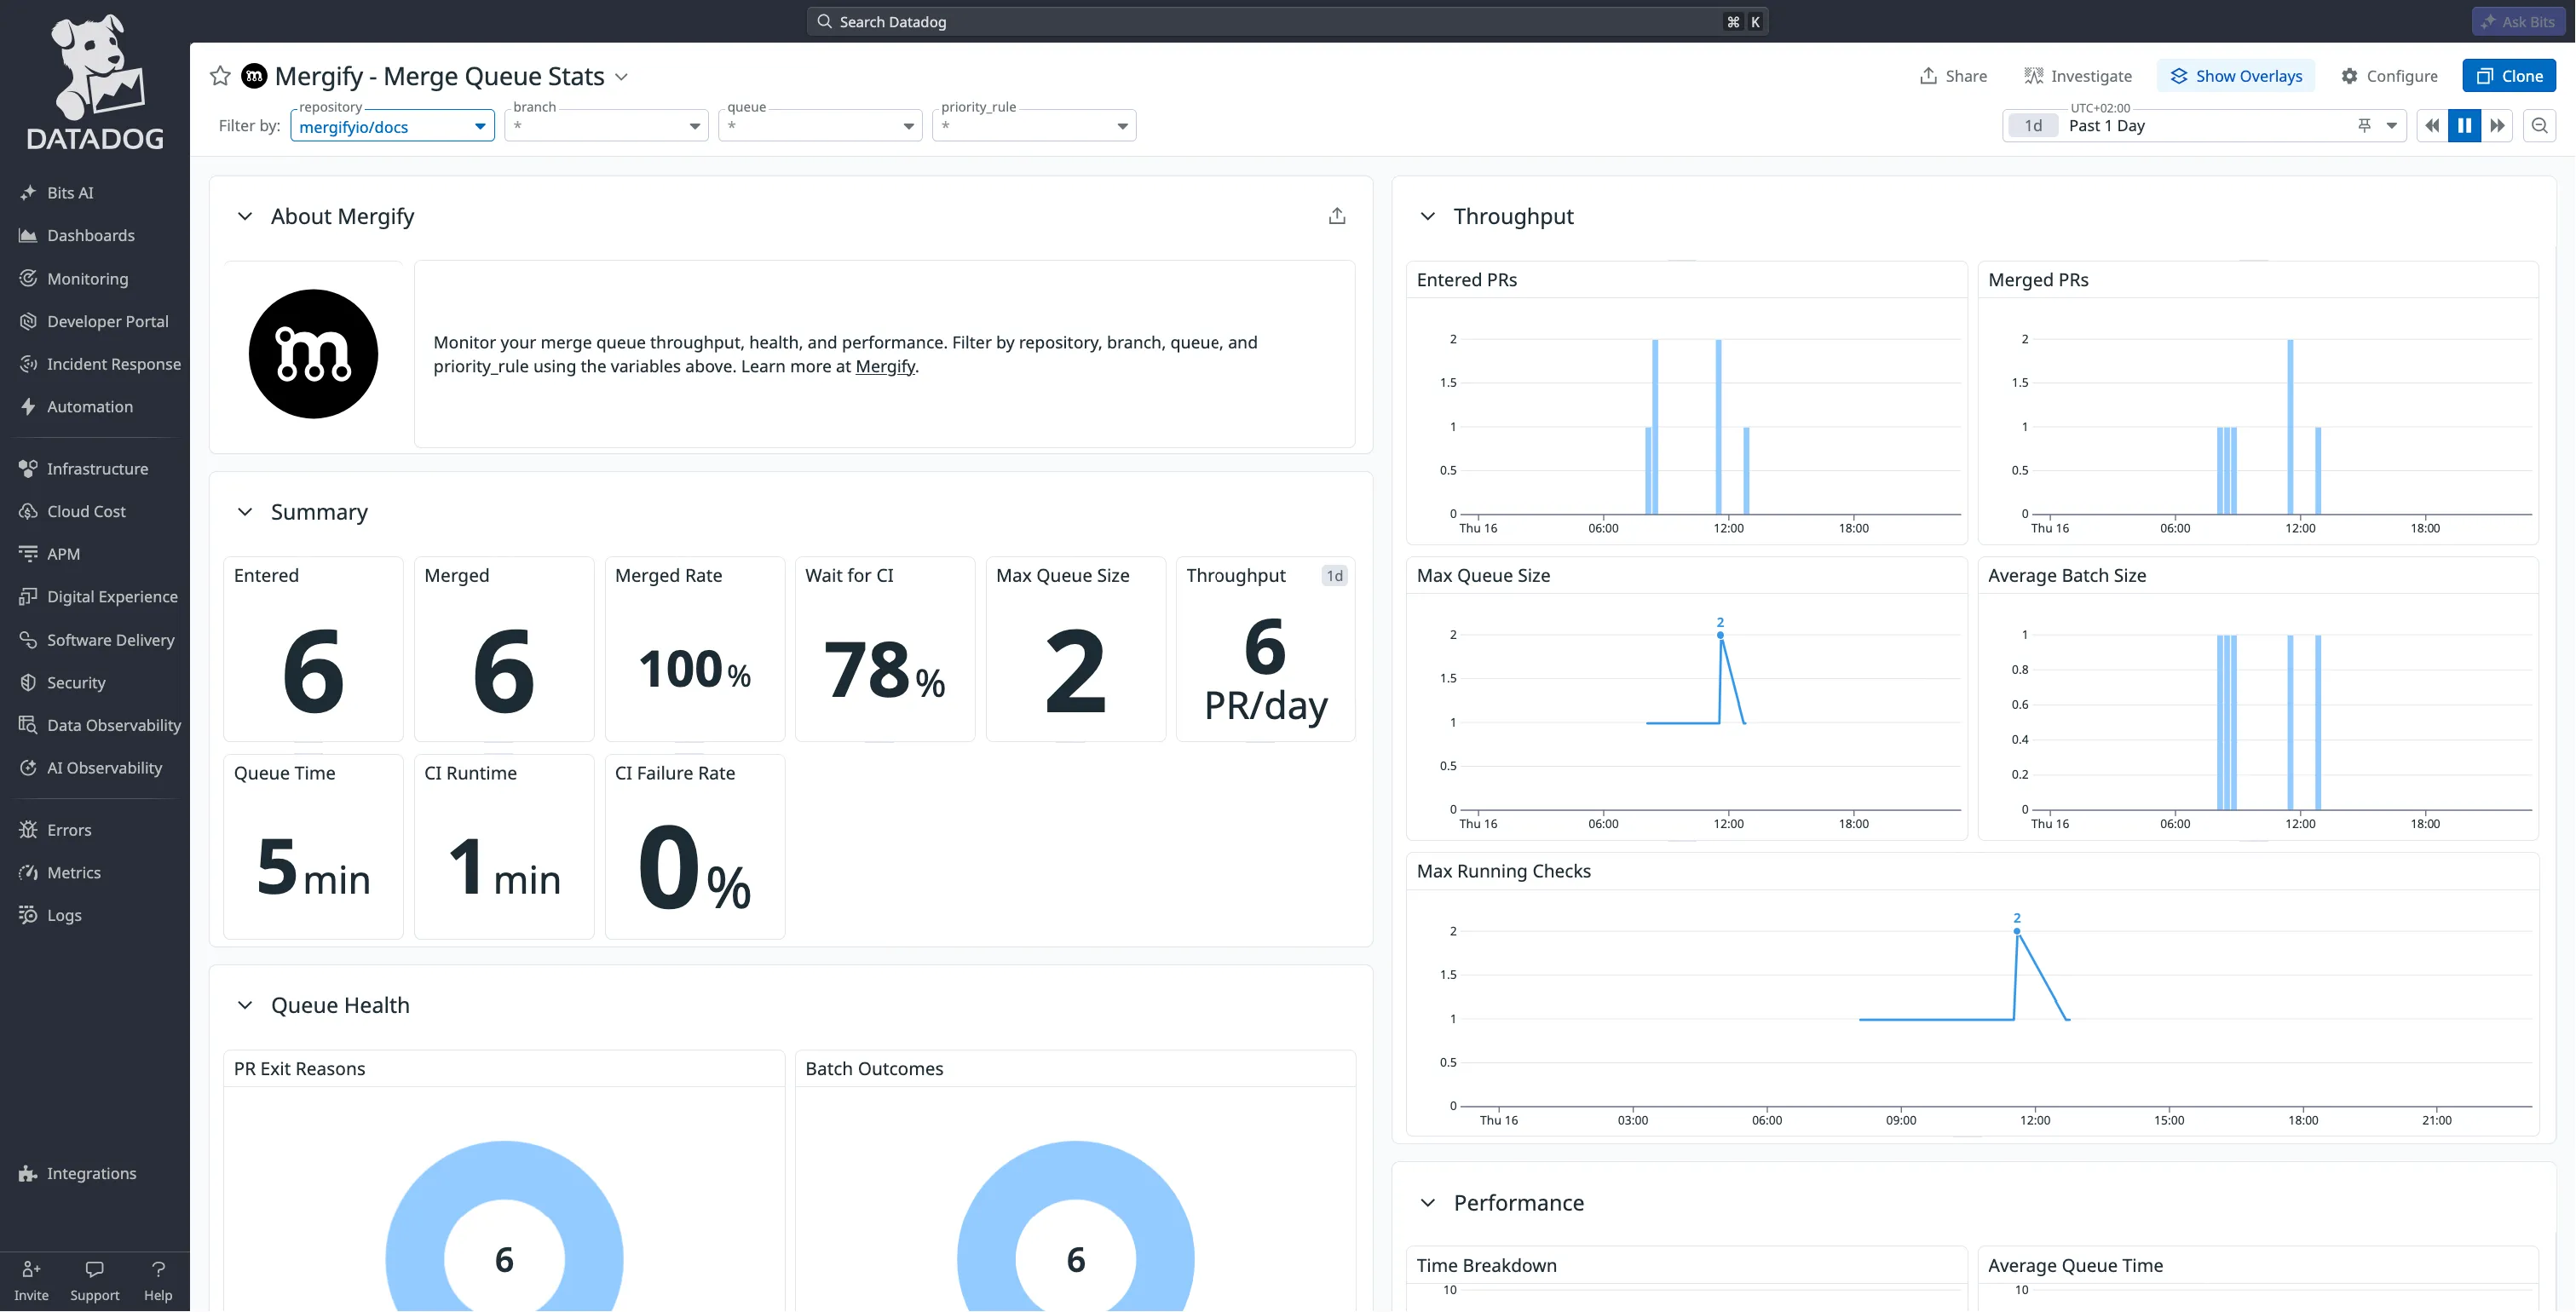
The Mergify tile ships
a Mergify - Merge Queue Stats dashboard that mirrors the merge queue
statistics page. In Datadog, search for mergify in your
account’s integration catalog, open the Mergify tile, and find the
dashboard under the Monitoring Resources tab. Clone it to adapt it to
your own repositories, or build your own from the metrics above.
Since the metrics are ordinary Datadog metrics, you can alert on them with monitors. Useful ones to start with:
-
mergify.queue.size.maxstaying above a threshold, which usually means CI capacity is the bottleneck. -
Average queued time trending up week over week.
-
Check retry recovery rate dropping, which points at genuinely broken tests rather than flaky ones.
-
mergify.queue.exit_reasoncounting anything other thansuccess, which means pull requests are leaving the queue without merging.
Learn more
Section titled Learn more-
Monitoring your merge queue: what each metric means and how to read it.
-
The Mergify tile on Datadog: setup from the Datadog side and the bundled dashboard.
Was this page helpful?
Thanks for your feedback!